
AI controls testing for a fintech.
Confidential UK fintech · agentic platform, concept to production
Testing one control used to take hours. It now takes minutes, and it runs across every control the team has. Each verdict the agent reaches is one click from the evidence behind it.
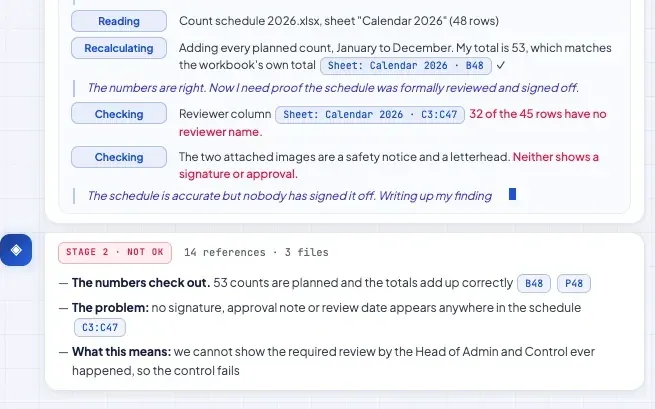
The agent console: the agent’s working notes and the cited verdict it reaches. Interface with fictional data.
Overview
Internal audit and controls teams spend most of their time on mechanical work: opening evidence files, re-adding spreadsheet totals, hunting for sign-offs, and writing up what they found.
OpenKit carried the work from first concept to a full production platform, combining strategic consulting with hands-on AI software development.
- One agent per control, re-performing the work on the evidence files themselves.
- Every factual claim is a live citation into the cell or the page region that supports it.
- Anything uncertain goes to a human reviewer, because the system is calibrated to raise a control whenever there is room for doubt.
Every control tested
The whole control population, where the team used to settle for a sample.
Hours to minutes
Per control, which is what makes testing all of them possible.
In production
The platform is live and generating revenue for the fintech.
Challenge
Hours per control, so teams test a sample
Testing a single control can take hours, and testing every control every period is impossible by hand, so teams sample, and exceptions slip through the gaps between samples.
The fintech asked a direct question: could an AI agent perform this testing end to end, at a standard an experienced reviewer would sign off, with every conclusion traceable back to its source?
Approach
A pipeline that works like a careful reviewer
We built a multi-stage pipeline, one agent per stage, that moves through a control the way a careful human does, with each stage answering one question before the next one starts.
Validate the rule
What exactly does this control require, and is the requirement grounded in the policy and standards that apply?
Verify the sources
Are the evidence files authentic, complete, and the right ones for the period under test?
Re-perform the work
Recalculate the numbers, trace the approvals, check the dates. Nothing is taken on trust.
Conclude
A verdict with plain-language reasoning: effective, exception raised, or refer to a human reviewer.
Each stage runs in isolation and produces its own cited finding, so a failure at any point is visible, explained and attributable. The agent hands an uncertain result to a human reviewer, and the calibration deliberately over-flags, so the system will raise a control for review long before it will wave one through.
Evidence
Every claim is one click from its evidence
The defining feature of the system is the citation trail, and every factual claim the agent makes is a live reference. Click a reference in a finding and the source opens beside the conversation: a spreadsheet opens on the right sheet with the cited cells highlighted, rendered with the workbook’s original formatting, and a document opens on the right page with the cited region drawn as a bounding box.
Checking a claim costs the reviewer one click.

Arithmetic
Numbers are recomputed in code
Arithmetic does not go through the language model. Wherever a control involves numbers, the agent writes and runs code in an isolated sandbox: it re-adds the schedule, reconciles the totals, and compares its own result with the workbook’s. The verdict follows from that computation, and when the agent’s total matches the cited cell, the agreement becomes part of the evidence trail.
Oversight
Questioning and overriding the agent
Testing runs as a conversation. The reviewer hands the agent a control and its evidence, watches the working notes stream in plain language, and can interrupt at any point to ask why a stage failed, request a re-test with corrected evidence, or challenge a conclusion. A reviewer can override a verdict with a written justification, and both the agent’s original finding and the override stay on the record.
Validation
Measured against experienced reviewers
We validated the system the way an audit methodology would demand. Controls were tested repeatedly and the agent’s verdicts were compared, stage by stage, against determinations made by experienced human reviewers. Where the agent disagreed with the humans, every mismatch was root-caused and written up, and the causes fed directly back into the design. The validation work settled how the system behaves:
Fail safe
The dangerous error is a false pass. The system is calibrated so that when it errs, it errs towards flagging a control for review.
Misses are investigated
Disagreements with human reviewers are treated as findings about the system, investigated with the same discipline the system applies to controls.

Assurance
Built for a regulated environment
The platform was built for a regulated financial-services context from the first commit, so the things a compliance team asks about last were settled first.
- Residency: EU data residency throughout, on serverless cloud infrastructure.
- Retention: Zero-retention document processing: evidence is parsed, never kept by third-party services.
- Traceability: Versioned prompts and full execution traces, so any verdict can be reproduced and inspected after the fact.
- Isolation: Isolated, ephemeral sandboxes for all agent-executed code.
- Access: Human-in-the-loop controls, role-based access and a complete override audit trail.
ISO 27001, ISO 9001 and Cyber Essentials are OpenKit certifications, and we operate to UK GDPR. The controls listed above are the ones built into this platform.
Result
From concept to commercial product
The fintech now has working papers in which every claim is one click from its evidence, and reviewers get their time back for the part of the job that actually needs human judgement.
The platform now sits at the heart of the fintech’s commercial offering, and it has helped them win large enterprise customers.
Alongside delivery, we supported the fintech in building their own internal development capability, so the product keeps growing in their hands.
Other engagements
What could your business do with AI?
Find out with experts who become part of your team. We uncover opportunities, get ideas working, and help your people build on the results. We reply within one working day.
Get in touch AI Engineering